

Last week I wrote that the internet was breaking. Unfortunately, not much has changed since…
Recent cyberattacks highlight widespread vulnerabilities in internet infrastructure (especially software foundations and exposed IoT/OT systems) and targeted physical-impact campaigns, such as the supermarket freezer attacks in Europe and many of the events on this list.
Governments across the Western world are now publishing vague warnings to “prepare” in the event of blackouts or malfunctioning infrastructure.


This week I want to write a bit about one of the reasons why the internet’s breaking. AI is the obvious cause, but one class of particularly useful AI stands out: abliterated, open-weight large language models.
That description is a mouthful, but it means obedient AI that does what the user wants.
As I wrote in September an AI model’s response depends on both its ability to perform a task and its willingness to attempt it. These are related but distinct:
Capability: What the model can successfully do, drawing on the knowledge and skills it acquired during training. This is a model’s “intelligence,” broadly speaking.
Willingness to comply: Which requests the model will answer, refuse, or answer only partially. Safety-oriented post-training helps shape these behaviors, teaching the model to withhold certain kinds of assistance even when it has the capability to provide them.
The labs call it “alignment” or “safety tuning,” but models are taught to say no to certain queries. “Abliteration” modifies this second category: learned refusal behavior.
The word “abliteration” is a combination of “ablation” and “obliteration.” Ablation refers to removing or disabling a particular component or function. Obliteration refers to erasing or destroying something completely. The developer FailSpy coined the name in 2024 as wordplay for ablating refusals to the point of obliteration.
If you’re interested in a more technical exploration of ablation, FailSpy’s original explanation is a good starting point, and there are more resources like this Alignment Forum post.
Houston, We’ve Had a Problem…
Capable, obedient models are making the internet, and the infrastructure that relies on it, harder to defend.
Abliteration makes clear the inevitable consequence of accessible AI: the ability to direct powerful intelligence now belongs to people whose objectives we support and people whose objectives we oppose.
None of this mattered much when AI was still a curious novelty to most of the world, which is to say before the start of this year. Since early 2026, however, agents have proven themselves to be formidable actors across the internet and the models that power them have improved dramatically.
For anyone who knows what they’re doing, both improving a model and reducing its learned refusals keep getting easier and cheaper, requiring less data and compute, and less expertise.
Capable, motivated criminals now have a powerful new weapon. In other words, the argument I made in Artificial Good Enough Intelligence (AGEI) is available to bad actors too. Criminals don’t need frontier models to succeed. They only need AI capable enough to achieve their objective, at a cost that makes the effort worthwhile.

Late last month, Epoch AI used Z.ai’s GLM-5.3 to develop working attacks against six recent Firefox releases in controlled tests. Published security fixes helped the model find weaknesses in versions people were still running, allowing it to exploit the delay before users received repairs. After a research program costing over $100,000, the team put the cost of exploiting each additional release at roughly $1,000. In this particular case, the model was unmodified (not abliterated) and still complied throughout, demonstrating that even without abliteration, certain models will pursue objectives capable of causing harm.
AGEI works just as well for criminals and hackers as it does researchers and tinkerers, especially when their targets have been found to feature critical vulnerabilities in their codebase (see PHP2Shell) or are running outdated software altogether (see freezer attacks in Europe and IoT writ large).
The frontier (“closed”) labs have understood the nature of this problem for a long time. For all of the criticism lobbed his way (mine included), Dario Amodei has been drawing attention to the potential danger of highly capable AI since he realized the power of scaling while he was at OpenAI (2016-2020).

Their current solutions involve withholding their most capable models until they can develop strong enough safeguards for public release. In addition to public safeguards, the labs have also made their models available to trusted partners in programs like Anthropic’s Glasswing initiative and OpenAI’s “Daybreak” program.


The primary problem with their strategy is obvious: legitimate defensive activity can involve the same code, commands, and techniques used in attacks. Safeguards may block those requests when providers cannot reliably establish the circumstances.
While I outlined this essay with Claude, for example, its cybersecurity safeguards triggered and automatically dropped me to a less capable model.

The most public example of this problem is the famous “Hugging Face” incident, where a swarm of OpenAI agents infiltrated the model hosting platform’s infrastructure. During the attack, commercial frontier APIs blocked the forensic material Hugging Face needed to analyze the situation and defend itself. Its engineers turned to an open model (Z.ai’s GLM-5.2), running on their own infrastructure, to keep responding. The attackers faced no such obstacle. OpenAI later said it had run its agents “with reduced cyber refusals for evaluation purposes.” The safeguards stopped only the defenders.
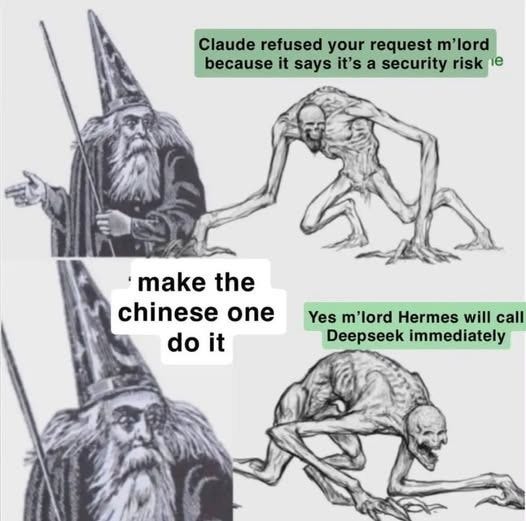
Which makes clear the other problem involved with safeguards and classifiers: concentration of power. When access is permissioned or comes with restrictions, the model providers bear an inordinate amount of power to decide who and what deserves access to their most powerful models.
Fighting Fire with Fire
Defenders, such as operational security teams, cybersecurity task forces, and “white-hat” hackers, need enough capability and freedom to investigate dangerous activity, understand and reproduce hostile behavior, and verify that their protections work. In some cases, supporting critical infrastructure (both public and private) may depend on it.
In a June study, researchers asked models to introduce a specified vulnerability into Python code, aiming to produce training material for software that detects security flaws. The largest model tested refused every request. After abliteration, it produced the requested vulnerability in roughly 88-97% of cases. Removing refusals made the model’s existing capability useful for generating security test material, allowing researchers to reproduce the behavior they wanted their defenses to recognize.
If legitimate defense encounters problems, then defenders themselves will turn to open models and abliteration as well.
What’s more, in many cases the world simply doesn’t know what it’s fighting against. Net new vulnerabilities (known as “Zero-Days”) are being discovered in real time, and fixes need to happen just as quickly.
If a Zero-Day is discovered by a benevolent security researcher, defenders may get a small head start on the patch. PHP2Shell shows how thin that margin is. Calif, a security firm working under OpenAI’s Patch the Planet program, found the flaws on August 1 and reported them to PHP ten days later. News of the bug leaked on October 20, ahead of the planned disclosure. Cloudflare saw the first attacks the next morning, hours before the patches shipped. If, on the other hand, a Zero-Day is discovered by an attacker, defenders may be fighting criminals who have already compromised a given system and attempting to mitigate the damage.
In either situation, time is of the essence. It’s clearly a good idea to remove most (if not all) of the obstacles in the way of those tasked with protecting the systems upon which our society depends to function properly. If the closed frontier labs won’t remove them, defenders can turn to abliteration, open models, or specially authorized hosted services. The necessary property is useful assistance that will help execute legitimate adversarial objectives in the name of safety and defense.
Abliteration as a Service
There are already companies selling this. Abliteration.ai sells access to modified open models, including GLM-5.3, that answer requests other providers refuse. Customers can use them through a browser or connect them to their own software through an API without modifying or operating the models themselves.
Abliteration.ai is making a business out of removing AI guardrails | TechCrunch
The company also makes its case for defensive use. Its agent-testing service offers to generate realistic attempts to make an assistant disclose confidential information, follow hostile instructions, or exceed its permissions. Customers describe the system and the failures they want to test. Abliteration.ai supplies the test material, and customers run those attempts in their own environments and evaluate the results.
Trust All the Way Down
The systems we depend on contain weaknesses that capable AI can help bad actors exploit. Protecting them increasingly depends on good actors with similar capabilities choosing to use them in our interests. Giving those people enough freedom to help us leaves us exposed to their mistakes and their intentions.


As I wrote in June, we have good reasons to scrutinize the commercial interests of companies offering that protection. Though they may mean well, centralized providers can sincerely want their customers to be safe and benefit from their dependence on their services, a clear conflict of interest.
Nevertheless, we will need people who understand these systems better than we do to form part of our defensive efforts.
When governments warn us to prepare for attacks on critical infrastructure, we tend to assume that protecting that infrastructure is also part of their job. Security is one of the basic things we expect from the state, including protection from threats we could never understand or address ourselves.
Gates is right that downloadable models can be modified to remove safeguards, making harmful assistance easier to obtain. He is also right that increasingly capable models are both more useful and more dangerous. His analysis is still a bit myopic. We haven’t figured out how best to manage this increase in capability, be they “closed” or “open” models.
But keeping complex digital systems secure depends on expertise and access distributed across the organizations that build, maintain, and operate them, often exceeding the capabilities of public institutions. Public cyber agencies already depend on relationships with these technical communities, as the UK’s National Cyber Security Centre describes. The institutions we expect to protect us rely, in turn, on people working under different arrangements.
We may look to public institutions for protection while the practical ability to provide it depends on people whose responsibilities, incentives, and relationship to us are quite different.
We already live with a considerable amount of this dependence. Most of us use software we could never inspect or repair ourselves, maintained by people we don’t know and won’t ever meet. AI expands what individuals can accomplish with that software, making their choices more consequential for everyone else.
Even well-meaning people can underestimate what they are setting in motion. In early November, agents run by Jake Runzer, a senior product engineer at Railway, probed rival cloud host Primcloud. Over 15 minutes they requested every secret on the platform and port-scanned its internal network twice. Primcloud founder Josh Manders said every attempt was blocked. Runzer said he had been using agents to sign up for and test similar platforms, with no malicious intent. He halted the system because it was “going off the rails and reaching too far.” Greater capability expands what an agent can do on someone’s behalf, including actions that person may never have anticipated when assigning the task. Someone can understand the outcome they want while having a much less complete understanding of how their agents might pursue it.

George Kurtz, CrowdStrike’s CEO, has announced an “AI Kill Switch”, intended to let security teams stop misbehaving agents within their organizations. As he writes, “The kill switch is the ultimate brake, and similar to racing, it allows us to go faster.”
In Good Faith
There is something uncomfortable about arriving here after spending so much time discussing safeguards. Our awareness of the potential for abuse grows alongside our need for capable people willing to help. Protecting ourselves means giving those people technical freedom while accepting that we can only imperfectly assess their intentions and competence.
The people who demonstrated how an open model could compromise Firefox also helped Mozilla repair the browser. Their experiment uncovered a previously undisclosed vulnerability, which they reported to the browser’s maintainers. Mozilla shipped a fix on October 27. Firefox users depended on both groups having the ability and inclination to do something useful with the finding.
Restricting access to these capabilities places considerable trust in whoever decides which people and purposes qualify. Making them widely available leaves us exposed to choices we cannot supervise. We have reasons to be uncomfortable with both arrangements, and our need for protection persists through that uncertainty.
I think we may have to come to terms with the faith that requires. Some part of our security depends on people having the means to cause harm and choosing to protect others.
